Football Stats for Betting — Which Numbers Matter and Which Mislead
 Available in US
Drowning in Data — the Modern Punter’s Real Problem
Ten years ago the problem was a lack of data. You had league tables, recent results, and whatever the newspaper previews told you. Today the problem is the opposite — there is so much football data freely available that most punters drown in it, mistaking volume for insight. I have watched friends spend two hours before a Saturday 3pm kick-off scrolling through possession percentages, shot maps, heat maps and passing networks, only to end up backing the same selections their gut would have chosen in five minutes. The data did not help because they did not know which numbers actually predict outcomes and which are noise dressed up as analysis.
Sports betting generates 57.1% of all UK online gambling revenue, and football accounts for the largest share within that. The data infrastructure supporting those markets has exploded — xG, xGA, PPDA, progressive carries, shot-creating actions, build-up speed metrics, pressing triggers. The list grows every season. But a model built on twenty inputs is not automatically better than one built on four, and in my experience the opposite is true. Overfitting to noisy metrics produces worse predictions than a lean model built on the metrics that genuinely carry predictive weight.
This guide is about subtraction, not addition. I am going to walk through the metrics I use, the metrics I have tested and abandoned, and the metrics that actively mislead punters who trust them without understanding their limitations.
Expected Goals — the Foundation, Not the Answer
I covered xG in depth in a separate piece, but it deserves a summary here because it is the single most important metric in modern football betting and also the most commonly misused.
xG measures shot quality by assigning a probability to each shot based on historical conversion rates from similar positions and situations. A team’s cumulative xG per match tells you how many goals their chances were “worth” on average. The metric is powerful because it strips out the randomness of finishing — a team that creates 2.0 xG per match but scores only 1.2 goals is underperforming its process, and that underperformance tends to correct over time. Backing that team before the correction is one of the most reliable edges in football betting.
Where xG misleads is when punters treat a single match’s xG as meaningful. One match produces a tiny sample of shots — typically 10 to 25 across both teams. The variance in that sample is enormous. A team can generate 0.3 xG and win 1-0 from a long-range screamer, or generate 3.5 xG and lose 0-1 because the goalkeeper had the match of his life. Neither single-match figure tells you anything reliable about future performance. I use rolling averages of eight to ten matches as my minimum sample, and I weight recent matches more heavily than older ones to capture tactical shifts and personnel changes.
Possession, Pass Completion and the Metrics That Flatter
Here is a confession: I spent an entire season in 2018 building a model that included possession percentage as a core input. The model performed worse than a stripped-down version that ignored possession entirely. That failure taught me more about football analytics than any success before or since.
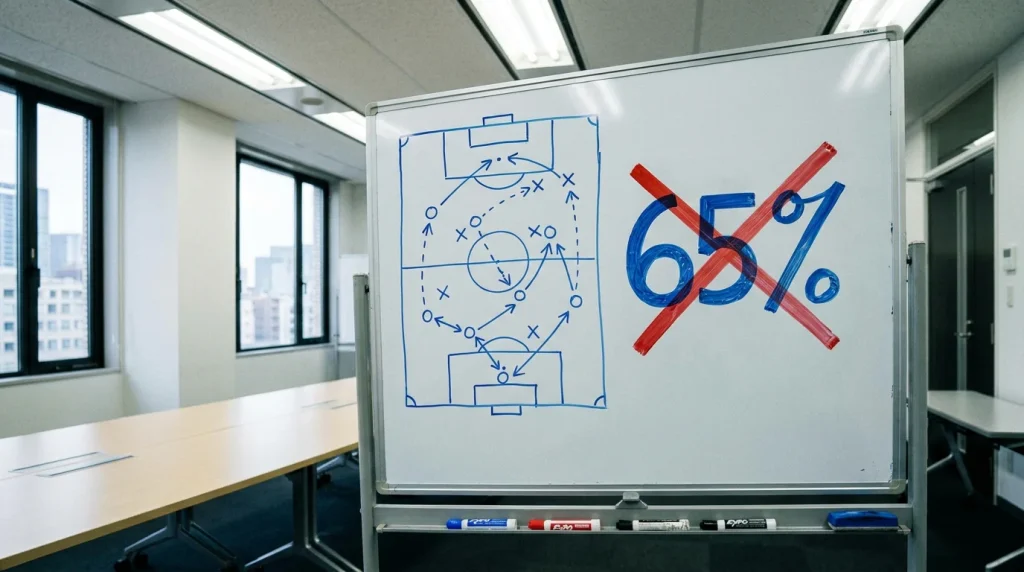
Possession percentage tells you how much of the ball a team had. It tells you nothing about what they did with it. A team can dominate possession at 65% by passing the ball sideways in their own half while their opponent sits in a compact low block, waits for a mistake, and scores on the counter. That team “dominated” the match statistically and lost it practically. Pass completion rate has the same problem — a team playing safe, short passes in non-threatening areas will post a 90% completion rate that looks impressive but reflects caution, not quality.
The AI-in-sports-betting market hit $10.8 billion in 2025 and is projected to surpass $60 billion by 2034, which means bookmaker models are increasingly sophisticated. They have already priced in the obvious surface-level stats. If your model relies on the same metrics the bookmaker’s model uses — possession, shots, pass completion — you are not finding edges. You are confirming the bookmaker’s existing pricing. The edge, when it exists, comes from metrics the bookmaker’s model handles less precisely or from combining metrics in ways that capture game dynamics the bookmaker’s model misses.
PPDA, Progressive Passes and Pressing Intensity
The metrics that have actually improved my betting model over the past three years are all related to how teams move the ball forward under pressure and how they prevent opponents from doing the same.
PPDA — passes per defensive action — measures pressing intensity. A low PPDA means the team engages the opponent quickly, typically high up the pitch. A high PPDA means the team sits deep and allows the opponent to build. For betting, PPDA is most useful as a contextual metric for interpreting xG. A team with low xGA and low PPDA is defending through active pressing — a sustainable process. A team with low xGA and high PPDA is defending deep and relying on blocks, which is harder to sustain across a full season.
Progressive passes — passes that advance the ball significantly toward the opponent’s goal — tell you about a team’s attacking intent and quality in a way that total passes and possession do not. A team completing 40 progressive passes per match is moving the ball into dangerous areas regularly, creating the raw material for chances. A team completing 15 progressive passes despite 60% possession is recycling the ball without purpose. I use progressive passes per match as a secondary filter for identifying attacking quality that xG alone might miss, particularly for teams whose xG is suppressed by poor finishing rather than poor chance creation.
Pressing triggers — the specific match situations that cause a team to press — are harder to quantify but increasingly available through advanced data providers. A team that presses aggressively after losing the ball in the opponent’s third creates turnovers in dangerous positions, which feed directly into xG. A team that only presses on goal kicks or set pieces creates fewer transition opportunities. I track pressing trigger data where available and use it to adjust my xG projections for specific fixture matchups. A high-pressing team facing an opponent that struggles under pressure will generate more xG than their season average suggests.
Building a Lean Model — Four Metrics, No More
After years of testing, expanding, trimming and retesting, my core betting model uses four metrics. Everything else is supplementary context, not a model input.
The four are: rolling xG per match (eight-match window, home-away split), rolling xGA per match (same window and split), PPDA as a defensive sustainability check, and a form-adjusted home advantage factor derived from each league’s historical home-win rate. That is it. Four inputs, weighted and combined into a probability estimate for each match-result outcome, fed into a Poisson model for scoreline and totals probabilities, and compared against the bookmaker’s implied probability to identify value.
I have tested adding progressive passes, shot-creating actions, aerial duel win rates, set-piece conversion rates, and half a dozen other metrics. None of them improved the model’s out-of-sample predictive accuracy by a statistically significant margin. Some actively worsened it by introducing noise that the model treated as signal. The UK remote betting sector generated GBP 7.8 billion in gross gaming yield in the year to March 2025, and the bookmakers pricing those markets have access to the same metrics I do — and more. The edge does not come from having more data. It comes from using less data, better. For a deep dive into how xG specifically translates into betting decisions across different markets, the xG betting guide covers the practical application in detail.
Which single football statistic is most useful for betting?
Expected goals per match on a rolling eight-to-ten-match basis is the single most predictive metric for football betting. It captures both attacking quality and defensive vulnerability in a way that goals scored and conceded cannot, because it strips out the randomness of finishing and goalkeeping. No other freely available metric comes close to xG"s predictive power across match result, totals and BTTS markets.
Why is possession percentage a poor predictor of match outcomes?
Possession percentage measures ball retention without capturing what the team does with that retention. A team can hold 65% possession while passing sideways in non-threatening areas, producing zero dangerous chances. Conversely, a team with 35% possession can create high-quality chances on the counter. The correlation between possession and match outcome is weak once you control for shot quality, which is why xG-based models outperform possession-based models consistently.
Articles
Written by the editors at Football Bet Today.
